SDPO: learn from your own correct attempts
Self-Distillation Policy Optimization (arXiv:2601.20802) samples a question several times and turns the attempts that succeed into teachers for the others. The teacher is the model itself reading the question with a correct attempt appended. The student reads the question alone. The loss pulls the student's next-token distributions toward the teacher's on the student's own attempt. The paper reports that SDPO reaches GRPO's accuracy with fewer samples.
|
Evolves |
model weights |
|
Signal |
one report per attempt with its score and its place in the sampling grid |
|
Loss family |
sdpo |
|
Package |
recipes/sdpo/ |
|
Pipeline |
reported feedback, one job per sampling grid |
|
Needs |
GPUs, and a backend that captures tokens and log-probs |
|
Example |
What it does #
The harness samples each question several times through Reef and scores every attempt. It reports each attempt with its score and its place in the grid. The recipe waits for the whole grid and trains on it in one step.
How Reef implements it #
SDPO has two pipeline stages (Training pipeline). SDPOSamples groups the reports of one grid and turns each rollout's report into one sample. SDPOJobData makes one job's data of one complete grid.
The teacher's request is the question with the first correct attempt by another rollout appended, in the reference implementation's words. An attempt whose question no other rollout got right keeps the plain request and a sample weight of 0. It stays in the step's mean and has no target. A grid whose attempts came from different policy versions is dropped and listed in the pipeline's status. Each sample carries its teacher's request in extra.reef.teacher. The training component renders the teacher sequence with the model's chat template: the teacher prompt, cut to max_teacher_prompt_tokens, followed by the attempt's response tokens. It leaves out a sample whose teacher sequence is longer than max_teacher_tokens, and counts it in the job metric unrenderable_samples.
The sdpo loss family is a thin family on the Slime backend's distillation base (Loss families) and its defaults are the reference's. The teacher is a copy of the weights that moves 5% toward the policy after every step. The loss is the Jensen-Shannon divergence over the student's top 100 tokens plus one bucket for the rest of the vocabulary. The student picks those tokens in one forward before the step, so the trainer needs zero dropout. Each token's loss is weighted by the capped ratio between the policy and the old-policy log-probs, which the actor computes with the weights of the job's start.
The report contract #
A report references one attempt and carries its score and its place in the grid. teacher_context is optional feedback for the teacher and the example leaves it empty.
{
  "references": ["<receipt of the attempt>"],
  "score": 1.0,
  "metadata": {"step": 3, "group": 12, "rollout": 5, "teacher_context": ""}
}
Configuration #
The deployment's top-level pipeline section configures the two stages. Each stage reads only its own config. The sample-to-job stage reads the values it needs from the record-to-sample stage:
-
record2sample (SDPOSamples) sets the grid and the teacher's windows. It is on-policy: a sample of an artifact that no longer serves does not train. SDPOJobData reads the grid and the teacher settings from it.
-
sample2job (SDPOJobData) sets the job size and what the teacher reads.
recipe:
  implementation: recipes.sdpo.recipe:SDPORecipe
pipeline:
  record2sample:
    config:
      groups_per_step: 32
      rollouts_per_group: 8
      max_teacher_tokens: 18944
  sample2job:
    config:
      job_samples: ${training.config.global_batch_size}
      include_environment_feedback: false
training:
  config:
    global_batch_size: 256           # groups_per_step x rollouts_per_group
  options:
    apply-chat-template-kwargs: '{"enable_thinking": false}'   # as the engine samples
Reef checks each stage's config when it loads the recipe. A stage key under recipe.config fails the deployment, and the error names the key's place in pipeline.
pipeline.record2sample.config.groups_per_step
32
questions in a grid.
pipeline.record2sample.config.rollouts_per_group
8
attempts at each question. At least 2.
pipeline.record2sample.config.max_teacher_prompt_tokens
10240
the rendered teacher prompt is cut to this many tokens.
pipeline.record2sample.config.max_teacher_tokens
18432
a sample with a longer teacher sequence does not train. Set it to the trainer's window. Must be at least max_teacher_prompt_tokens.
training.options.apply-chat-template-kwargs
none
the chat template arguments, as a JSON object, with which the component renders each sample. Set them as the engine samples, for example '{"enable_thinking": false}'.
pipeline.sample2job.config.job_samples
required
the fewest samples of one job; at most the grid's rollouts. Set it to the grid.
pipeline.sample2job.config.success_reward_threshold
0.5
an attempt at or above this score is correct.
pipeline.sample2job.config.allow_own_success_as_demonstration
false
let a correct attempt read its own response.
pipeline.sample2job.config.remove_thinking_from_demonstration
true
strip <think> blocks from the demonstration.
pipeline.sample2job.config.include_environment_feedback
false
add the report's teacher_context to the teacher's prompt.
pipeline.sample2job.config.environment_feedback_only_without_solution
true
use the feedback only when no correct sibling exists.
SDPOSamples also takes the sample assembly's keys (accept_multi_turn_policy_samples, realign_threshold and scaffold_tolerance). One job's data is one grid. job_samples must not exceed the grid's rollouts (groups_per_step x rollouts_per_group); with a larger one the scenario's pipeline fails to build. Set it and Slime's --global-batch-size equal to the grid to train one optimizer step per grid, as the example does. Leave pipeline.sample2job.config.buffer_size at its default, job_samples: a larger value can put two grids in one job's data.
Slime takes --loss-type custom_loss and --disable-compute-advantages-and-returns, and refuses --use-rollout-logprobs. The family adds its own flags:
--sdpo-teacher
self
self is the model itself. separate is another checkpoint set by --sdpo-teacher-checkpoint.
--sdpo-divergence
jsd
forward, reverse or jsd. --sdpo-jsd-beta is the teacher's weight in the mixture and defaults to 0.5.
--sdpo-top-k
100
tokens per position the divergence is computed on. 0 keeps the whole distribution.
--sdpo-top-k-source
student
who picks the tokens, student or teacher.
--sdpo-top-k-distribution
tail
tail keeps the rest of the vocabulary as one bucket. renormalized conditions on the picked tokens.
--sdpo-teacher-update-rate
0.05
fraction of the policy mixed into the teacher after every step. 0 freezes the initial weights.
--sdpo-importance-sampling-level
token
token weights each token by its own ratio. sequence averages the ratio over the response.
--sdpo-importance-sampling-cap
2.0
cap of the importance weight. 0 disables the correction.
--sdpo-skip-response-tokens
0
response tokens at the start of every attempt left out of the loss.
The sampled reverse-KL mode also accepts score centering for training/inference mismatch. Score centering needs the sampler's recorded top-K, which samples that serving recorded do not carry. See Score centering. The default JSD over top-K plus a tail bucket does not support it.
Run the example #
The example trains Qwen3-8B on the Chemistry split of SciKnowEval on eight GPUs: four for the actor and four for the serving engines. Each step samples 32 questions eight times and the test split is scored every five steps. The example's README describes the protocol.
cd recipes/sdpo/examples/sciknoweval
hf download Qwen/Qwen3-8B --local-dir ~/models/Qwen3-8B
./run.sh
Results #
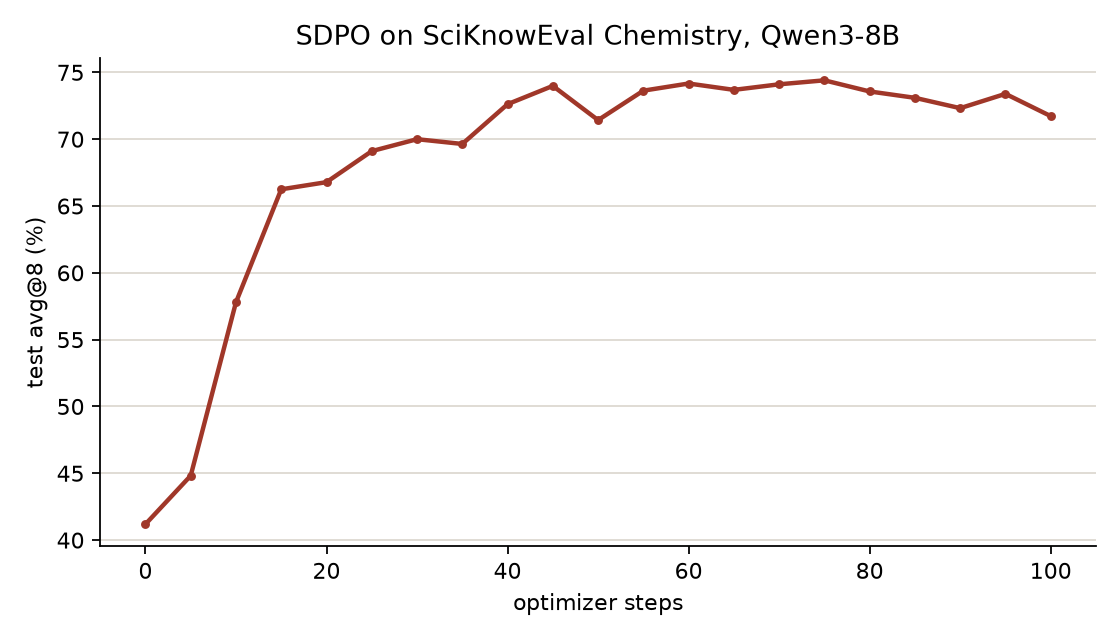
One run of 100 steps. Test accuracy goes from 41.2% to 74.4% at step 75 and ends at 71.7%. The rollouts stay diverse and a question seen a second time is answered no better than the rest of the grid.
Related guides #
-
Inference and feedback quickstart: learn the request, receipt, and report workflow.
-
Train model weights from agent feedback: set up the GPU stack and inspect published updates.
-
Loss families: how a family such as sdpo plugs into the Slime backend, and the distillation base it is built on.