SDFT: learn from demonstrations without forgetting
Self-Distillation Fine-Tuning (arXiv:2601.19897) learns from demonstrations on policy. The model that reads a demonstration in its prompt is the teacher. The same model without the demonstration is the student. The student samples the response and the loss pulls its next-token distributions toward the teacher's. The paper reports higher new-task accuracy and less forgetting than supervised fine-tuning on the same demonstrations.
|
Evolves |
model weights |
|
Signal |
one report with the demonstration as teacher_context per rollout |
|
Loss family |
sdft |
|
Package |
recipes/sdft/ |
|
Pipeline |
reported feedback, singleton |
|
Needs |
GPUs, and a backend that captures tokens and log-probs |
|
Example |
What it does #
The harness sends a request through Reef. It gets a demonstration of the response from somewhere else such as a reference solution or a stronger model. It reports the demonstration against the request's receipt. With a job_samples and a batch size of 1, each report is one training step.
How Reef implements it #
SDFT has two pipeline stages (Training pipeline). SDFTSamples makes each report its own record set and turns it into one sample. The shared DistillJobData stage puts the samples into job data in arrival order. One job's data holds pipeline.sample2job.config.job_samples samples.
SDFTSamples extends the shared DistillSamples. DistillSamples turns every TeacherContextReport into one TrajectorySample: the student's call as an ATIF trajectory, with the teacher's request in extra.reef.teacher. The training component renders both with the model's chat template. The teacher sequence is the teacher's request rendered with the generation prompt and followed by the student's response tokens. A teacher sequence longer than max_teacher_tokens does not train: the component leaves the sample out and counts it in the job metric unrenderable_samples.
SDFTSamples adds the demonstration block to the request's final user message. It adds the block as a new user message when the request ends in a tool result. context_template sets the block's text and its default is the reference implementation's wording. A harness that needs another layout subclasses SDFTSamples and overrides teacher_request. The deployment names the subclass in pipeline.record2sample.module.
The sdft loss family is a thin family on the Slime backend's distillation base in reef/train/slime_backend/distill/ (Loss families). It sets the reference's defaults and runs as a custom_loss. Before each step the base runs one forward pass over every sample's teacher sequence and keeps the teacher's next-token distribution at each response position. The loss compares the student's distribution at the same positions with it.
The teacher is the model itself (--sdft-teacher self) and --sdft-teacher-update-rate sets how its weights move. The default is 0.01. The teacher starts as a copy of the initial weights and moves 1% toward the policy after every step. A rate of 1 makes the current policy the teacher and a rate of 0 freezes the initial weights. In the skill stream example a teacher that follows the policy drifted with it and training collapsed. The example freezes the teacher with a rate of 0.
The loss is the per-token divergence over the full vocabulary. The forward KL is the default and the reverse KL and the generalized JSD are switches. A top-K representation of the teacher is another switch. Each sample contributes the mean over its trained response tokens. That mean is weighted by the truncated importance-sampling ratio between the policy and the old-policy log-probs. The actor computes those with the weights of the job's start. The stage is on-policy, so the ratio is exact.
The sampled reverse-KL mode also accepts score centering for training/inference mismatch. Score centering needs the sampler's recorded top-K, which samples that serving recorded do not carry. See Score centering. The default full-vocabulary forward KL does not support it.
The report contract #
A report references one inference record and carries the demonstration as metadata.teacher_context. A score is optional metadata and the recipe never trains on it.
{
  "references": ["<receipt of the student's request>"],
  "metadata": {"teacher_context": "<the demonstration>"}
}
Configuration #
The deployment's top-level pipeline section configures the stages. Each stage reads only its own config.
recipe:
  implementation: recipes.sdft.recipe:SDFTRecipe
pipeline:
  record2sample:
    config:
      max_teacher_tokens: 8192
  sample2job:
    config:
      job_samples: ${training.config.global_batch_size}
training:
  config:
    global_batch_size: 32
Reef checks each stage's config when it loads the recipe. A bad context_template or an unknown key fails the deployment. A stage key under recipe.config also fails it, and the error names the key's place in pipeline.
pipeline.record2sample.config.max_teacher_tokens
0
the training component leaves out a sample with a longer teacher sequence and counts it in unrenderable_samples. 0 disables the check. Set it to the trainer's window.
pipeline.record2sample.config.context_template
the reference's block
the text added to the final user message. {context} marks where the demonstration goes.
pipeline.sample2job.config.job_samples
required
rollouts in one job. Set it to training.config.global_batch_size so that one job is one optimizer step.
training.config.global_batch_size
rollouts in one optimizer step. Reef passes it to Slime as --global-batch-size. Each sample is its own data-parallel unit.
SDFTSamples also takes the sample assembly's keys (accept_multi_turn_policy_samples, realign_threshold and scaffold_tolerance).
Slime takes --loss-type custom_loss and --disable-compute-advantages-and-returns, and refuses --use-rollout-logprobs. Set --apply-chat-template-kwargs to the serving engine's chat template arguments (Chat template arguments). The family adds its own flags:
--sdft-teacher
self
who scores the samples. self is the model itself reading the demonstration. separate is another checkpoint of the same architecture set by --sdft-teacher-checkpoint.
--sdft-divergence
forward
forward is KL(teacher || student). reverse is KL(student || teacher). jsd is the generalized Jensen-Shannon divergence and --sdft-jsd-beta sets the teacher's mixture weight with a default of 0.5.
--sdft-top-k
0
keep the teacher's top-K log-probs and its log-prob at the sampled token. 0 keeps the whole distribution.
--sdft-teacher-update-rate
0.01
fraction of the current policy mixed into the teacher's weights after every step. 1 makes the current policy the teacher and 0 freezes the initial weights.
--sdft-importance-sampling-cap
2.0
cap of the truncated importance-sampling weight. 0 disables the correction.
--sdft-skip-response-tokens
0
response tokens at the start of every sample left out of the loss. The paper's runs used 3.
The teacher pass keeps one float16 block per sample on the host between the pass and the step. The block has one row per response token and one column per vocabulary entry on the rank. That is about 2 GB for a 16k-token response of a 248k-vocabulary model at tensor parallel 4. Size max_teacher_tokens with that in mind for long contexts. A moving teacher copy also costs the actor's weights once more on the host per rank.
Run the example #
The example trains one model on Tool Use and then on Science Q&A on an eight-GPU stack: four GPUs for the actor and four for the serving engines. A judge scores both skills every ten steps during both stages. The example's README describes the protocol and the settings.
cd recipes/sdft/examples/skill_stream
hf download Qwen/Qwen2.5-7B-Instruct --local-dir ~/models/Qwen2.5-7B-Instruct
./run.sh
Results #
The figure shows one run of SDFT and one run of an SFT control on Qwen2.5-7B-Instruct.
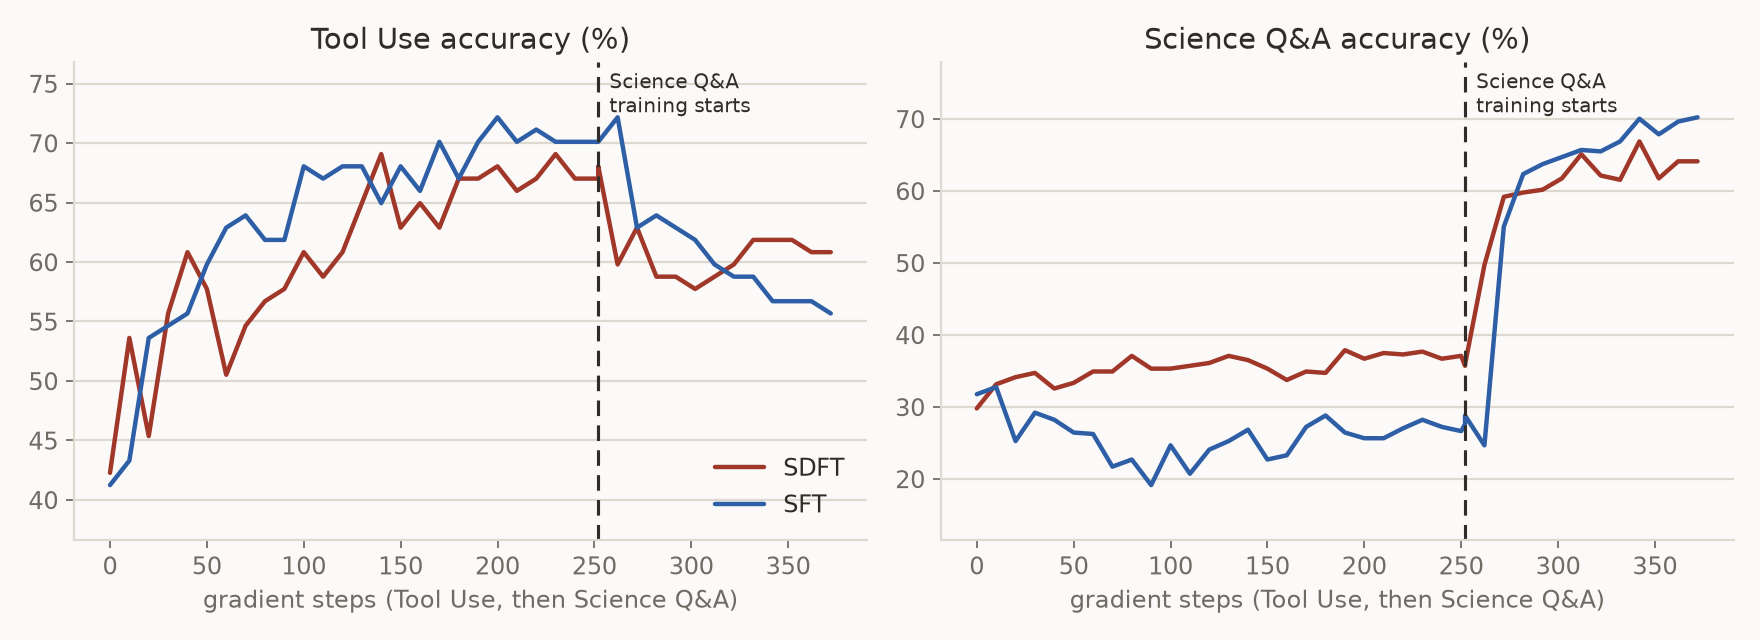
Tool Use training comes first and both methods learn it to about the same level. SFT pushes Science Q&A below the base model and SDFT does not.
Science Q&A training comes second and both methods learn the new skill. SDFT forgets only a little Tool Use and SFT forgets much more.
Related guides #
-
Inference and feedback quickstart: learn the request, receipt, and report workflow.
-
Train model weights from agent feedback: set up the GPU stack and inspect published updates.
-
Loss families: how a family such as sdft plugs into the Slime backend, and the distillation base it is built on.